Repository navigation
Compute perplexity over prompt - #270
Conversation


|
Got results for 7B, ctx=1024: |

|
This is indeed very cpu time consuming. I had it running for 25min and only got this far: |
this is likely related to #213 |


|
Very useful work. I think this can be significantly made faster if we have the option for the |

|
@glinscott How is it you're seeing Anyway I ran it on the 7B FP16 model before your most recent commits (at commit e94bd9c), with and got
|
Yes, thanks! I was prototyping this last night, just got it working (I think). Current output with: So, it's consistent with the old one, but much more accurate (256x more tokens for 512 size window). |
I did exactly the same 🙈 . but with a slightly different batch size. |
@glinscott can you check your wikitext file is correct? |
There are a couple of possibilities. I get this error tokenizing: So, I assume it truncates the string there? Do other folks not see that? Other possibility is my dataset is wrong, can someone double check? It's 1290590 bytes. |
hmm, so file hash checks out |
|
One thing to note, I don't think the Can someone try adding this debugging printf() in? I get this: |
|
you should check your model files #238 |
I get this: |
|
Same results as @Green-Sky here. @glinscott I suspect you need to rebuild your models; you can check against the md5 hashes listed in #238. I don't see the "failed to tokenize string" message you report, either. I'm guessing you did the conversion before #79. |
|
Sure enough, my model was busted! Ok, I see consistent results now :). Now, at 22 seconds per inference pass, it's ~4 hours to do wikitext-2. So, would be great to see if we can get representative results from a much smaller subset. |
|
I'll do a run with: And log all the perplexities along the way. Once it starts to converge, it's probably a good sign we can cut the dataset off at that point. With the new method, it seems to be converging much faster hopefully. But we will see! |
|
I asked GPT4 for some stats advice, and it recommended:
We will see :). That's [150/649] in our model (256 samples per evaluation). There are some big assumptions about uniform distribution of data in there which probably don't hold for wikitext2, but probably still reasonable. Most recent results do look like they are converging nicely: |
|
I merged in #252 locally and am seeing a much better score: This was done using the same model (7B FP16) and settings I used above (except with the model re-built to use the new tokenizer, of course), and without 91d71fe, so the numbers should be directly comparable to the ones I got above ( I'll re-run both scenarios using the new logic in this branch but I expect very similar results. (Edit: yeah, pretty similar: |

|
@bakkot - wow, that is an incredible delta. Interesting, so the tokens must be subtly off with the existing tokenizer? |
|
Not really subtly, as reported in e.g. #167. Honestly it's impressive that it does as well as it does with the broken tokenizer it's currently using. |
|
Ok, well, for the 7B model at 4 bit quantization, the perplexity appears to be 12.2-12.9 or so. Doing a little bit of a random walk. Going to stop at 470 since I'm excited to try out #252 :).
|
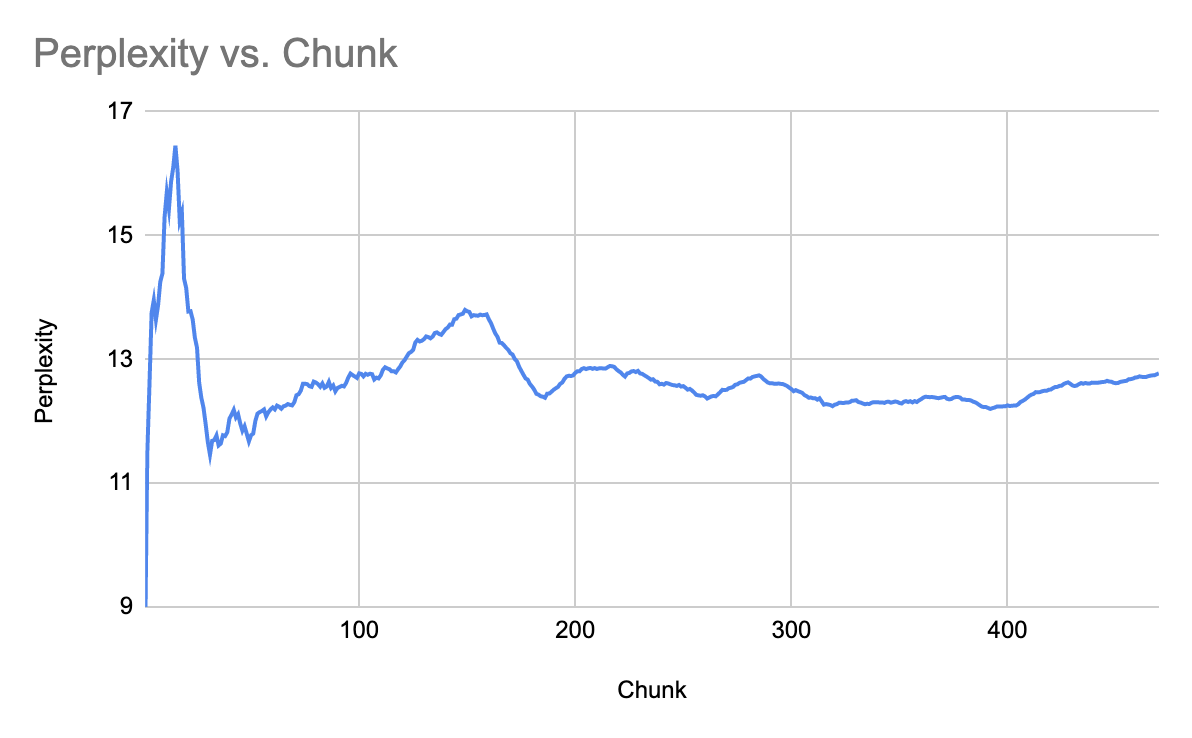
|
@glinscott Sidebar - the perplexity scores for chunks in wiktext aren't independent, because some articles are easier than others and there's multiple chunks per article. (So e.g. you might have ten chunks in a row from a really difficult article, each of which will raise the perplexity. With independent chunks that sort of consistent change in one direction would happen only very rarely.) That means perplexity isn't going to converge as fast as it should. So you might want to randomize the order in which chunks are processed, as in // Different parts of the prompt are likely to vary in difficulty.
// For example, maybe the first half is easy to predict and the second half is hard.
// That will prevent scores from converging until the whole run finishes.
// So we randomize the order in which we consume each part of the prompt,
// so that the score converges towards the real value as rapidly as possible.
std::mt19937 gen(0x67676d6c); // use a fixed seed so results are reproducible; this seed is `ggml` in hex
std::vector<int> indexes(seq_count);
std::iota(indexes.begin(), indexes.end(), 1);
std::shuffle(indexes.begin(), indexes.end(), gen);
for (int i : indexes) {instead of for (int i = 0; i < seq_count; ++i) {I haven't run this code, nor tested if it actually makes a difference in how fast the scores converge, but I expect it or something like it should work. |
|
Results for 4-bit quantization are looking great so far with #252 merged in as well! |
|
I captured the perplexity for each chunk separately (using 7B FP16, with #252 merged in). From there I looked into how good the measurement would be if you used fewer chunks, assuming you consume the chunks in a random order. Keep in mind there's 655 chunks total. The (empirical) 90% confidence intervals for the difference from the final perplexity (for my specific conditions) after a specific number of chunks are:
Determining whether you can get away with fewer chunks will depend on the size of the effect you're looking at - e.g. the fixed tokenizer is obviously better after only 10 chunks, but confirming the presence of smaller effects (like from improved quantization strategies) will require significantly more. code/data if you want to reproduce my results// this is javascript
let data = [
4.2337, 5.2897, 7.7770, 8.3287, 6.8390, 6.0943, 7.7364, 7.2585, 10.1792, 9.7338, 9.8226, 7.5937, 6.3308, 8.0002, 11.8844, 3.3917, 5.5408, 6.1756, 2.6730, 6.4901, 4.9989, 3.6592, 5.7682, 4.5201, 6.2160, 3.2217, 2.8567, 3.7494, 3.7945, 2.5883, 4.7733, 6.2793, 4.0443, 6.6725, 6.4370, 7.0745, 5.6611, 6.0521, 7.0657, 8.0699, 6.0984, 7.5405, 4.3730, 8.8372, 5.9219, 4.7395, 6.8133, 4.7350, 5.8450, 4.1329, 5.5502, 5.2692, 8.6583, 4.9914, 4.6868, 7.5662, 6.9880, 6.9894, 6.8970, 8.8414, 5.4384, 10.6731, 8.1942, 6.8570, 9.3563, 6.5627, 7.2757, 7.0825, 7.8798, 8.5397, 7.7570, 8.8057, 12.2151, 6.5003, 7.2832, 7.1812, 7.1461, 5.2082, 8.8034, 5.7541, 7.2228, 6.5905, 3.2219, 4.8862, 5.2106, 4.6112, 2.4795, 4.2595, 4.5617, 4.9153, 8.4723, 5.5482, 6.1128, 5.8297, 9.2492, 6.0519, 5.5583, 5.5216, 4.9173, 5.9582, 8.9768, 5.6014, 8.5170, 6.8875, 6.0951, 8.1004, 6.0354, 7.6947, 5.6168, 5.7427, 9.1345, 8.8376, 6.3986, 5.7434, 6.8633, 5.2115, 6.7495, 10.5116, 9.3441, 11.9780, 8.2422, 10.0067, 12.7040, 8.8324, 5.2965, 13.4408, 12.8634, 11.5266, 4.7939, 7.5777, 5.9655, 5.5261, 4.9038, 7.8649, 5.9049, 5.1198, 5.4877, 4.3806, 5.0965, 5.8914, 3.3561, 5.8583, 3.2323, 3.9742, 5.1125, 4.7900, 6.7743, 6.3185, 5.5245, 5.6687, 6.5638, 4.9464, 4.2488, 5.0675, 7.3592, 5.5228, 9.4368, 6.9210, 6.9797, 6.6831, 8.4606, 3.0650, 4.6591, 3.4063, 2.7900, 3.0231, 2.3005, 2.6896, 4.1826, 4.5053, 2.9034, 3.7563, 3.7867, 2.5532, 3.2104, 4.2681, 3.3105, 3.0264, 3.5613, 4.4102, 3.0667, 3.3960, 3.8231, 5.6702, 4.6170, 6.0197, 7.0675, 5.1326, 10.0308, 5.9919, 11.3845, 9.7865, 9.9764, 8.3787, 11.7139, 9.7893, 11.7055, 9.7135, 6.5766, 7.0163, 5.0125, 11.0156, 7.5948, 5.6769, 8.4561, 7.5776, 5.2701, 7.9725, 6.8910, 7.1792, 8.6991, 7.6900, 8.6591, 6.5381, 6.6024, 9.9117, 11.4651, 9.6110, 6.0322, 5.3760, 5.0621, 5.6246, 4.3323, 4.6806, 5.2827, 12.8015, 8.1204, 7.3919, 7.6432, 5.4063, 11.2815, 3.9873, 3.3158, 3.5056, 2.8041, 4.7094, 4.1956, 6.7119, 3.4211, 4.0789, 6.4766, 6.9613, 5.6383, 3.8569, 5.3274, 3.8636, 3.7660, 4.4742, 5.4093, 7.2289, 4.4956, 5.2353, 4.0107, 4.7802, 3.7488, 2.8184, 3.5604, 4.2093, 5.3541, 4.1740, 4.9184, 4.6309, 4.6749, 2.1799, 5.7219, 5.4113, 4.3672, 8.6913, 5.3731, 6.1470, 8.3038, 6.8235, 5.9549, 6.5837, 8.5758, 7.7327, 12.1389, 9.3534, 9.1320, 6.7431, 9.3347, 7.7855, 11.8079, 8.6349, 8.8769, 11.3166, 5.8538, 7.8667, 4.0560, 2.8534, 2.9460, 2.9278, 3.1373, 6.6050, 5.6842, 7.4505, 5.5637, 6.8299, 5.2548, 3.4957, 5.9363, 4.0149, 3.8561, 3.8802, 4.9512, 3.1070, 6.6027, 6.8806, 2.6353, 4.4386, 4.2173, 6.5665, 4.3896, 5.3577, 2.5667, 4.4052, 2.4796, 1.9780, 10.9267, 11.2068, 7.4261, 4.6996, 4.0354, 5.0048, 10.1574, 5.8825, 6.5496, 7.2039, 8.0570, 6.7768, 11.5410, 4.9996, 8.5831, 4.3073, 4.1795, 7.2409, 5.1631, 5.6205, 4.3670, 4.5893, 9.2200, 6.8801, 7.6852, 5.9022, 6.0188, 5.0642, 7.4118, 7.1476, 6.6982, 4.8392, 6.1443, 5.8701, 4.1545, 5.8907, 7.9460, 7.0058, 4.7597, 10.0613, 6.8521, 4.7857, 5.7337, 8.9369, 11.5146, 8.5051, 8.0402, 6.3870, 9.9484, 5.0987, 6.2364, 6.4576, 4.2600, 7.9318, 7.8497, 5.3683, 5.9516, 8.9665, 4.4904, 6.9869, 8.5304, 3.6020, 4.7592, 4.3036, 5.6554, 5.7098, 5.5246, 5.7023, 5.8297, 4.6599, 4.2254, 3.7789, 3.5960, 4.5255, 5.2527, 6.9731, 5.4062, 3.6407, 9.3482, 7.5259, 9.8064, 5.9531, 6.4362, 6.2962, 6.7262, 9.0811, 3.0848, 4.7268, 5.7033, 6.5912, 12.8079, 12.4113, 12.7754, 17.2818, 12.5417, 9.9668, 8.6653, 10.1074, 13.5201, 7.5909, 9.4968, 10.9255, 13.2899, 7.9184, 9.7576, 12.5443, 10.9062, 9.3986, 8.1765, 10.7153, 8.5812, 10.7370, 16.0474, 7.9101, 5.7778, 4.5653, 6.4762, 7.2687, 11.9263, 10.3103, 4.8934, 5.7261, 4.2609, 5.4918, 6.6898, 6.2934, 5.3325, 7.2188, 7.5185, 8.2033, 5.1273, 6.5011, 4.5670, 2.2386, 3.2372, 3.9893, 6.5170, 8.6117, 7.0107, 5.1495, 6.3412, 11.4701, 4.9500, 5.4811, 8.1177, 5.5823, 4.9553, 3.3866, 6.1404, 5.9408, 7.0779, 6.2677, 4.2244, 8.4411, 4.0633, 6.6431, 3.7769, 6.8590, 3.4788, 5.5537, 9.3246, 8.5652, 6.9801, 4.2857, 4.3862, 7.0454, 5.1355, 3.8384, 5.9033, 5.0303, 4.1490, 4.9914, 4.7928, 3.8402, 4.8503, 5.2423, 5.7663, 4.4227, 3.8162, 5.2343, 4.2511, 2.8094, 3.4875, 6.0975, 5.7161, 2.9156, 7.1691, 6.3762, 3.6819, 4.2773, 5.7032, 7.9792, 8.8110, 8.0352, 7.0775, 10.1292, 3.7952, 5.5346, 6.5626, 5.8085, 7.7367, 7.3946, 6.6608, 7.5490, 6.3721, 9.8001, 7.8648, 6.5025, 7.0076, 3.8873, 6.2564, 3.9161, 5.4713, 8.9538, 7.3572, 5.1763, 7.2523, 3.7586, 4.9993, 9.2871, 6.6082, 8.3411, 6.1726, 6.6453, 6.9063, 6.6387, 5.0784, 6.4587, 4.1723, 3.9443, 6.0791, 4.6138, 4.4106, 4.9176, 4.3316, 4.9980, 4.5371, 5.7626, 7.3694, 4.2320, 5.8014, 5.9095, 6.1267, 4.9075, 5.7717, 8.9320, 7.2476, 5.8910, 4.9010, 6.3294, 5.2988, 7.7972, 6.2766, 6.5831, 6.0055, 4.2898, 5.6208, 5.9260, 5.2393, 5.0046, 6.2955, 3.2518, 4.2156, 5.3862, 6.4839, 6.1187, 2.9040, 3.1042, 6.2950, 9.5657, 9.8978, 8.0166, 7.3498, 5.3361, 4.3502, 6.6131, 4.7414, 8.2340, 4.8954, 4.4713, 7.3732, 5.7101, 5.1141, 6.5039, 7.8757, 6.4675, 8.4179, 7.3042, 5.0399, 4.3175, 6.4821, 8.5142, 5.0135, 7.7970, 4.1496, 3.6323, 2.8987, 7.8440, 3.2591, 3.6729, 3.4526, 1.4961, 2.9882, 5.0225, 6.9797, 6.2451, 6.0565, 5.2908, 7.4791, 6.0146, 5.6742, 8.2883, 10.7090, 10.6945, 5.1382, 8.5528, 6.3640, 4.1532, 4.1070, 7.6952, 4.2944, 6.5832, 6.0564, 11.9188, 7.4791, 6.7621, 4.8915, 9.0851, 3.8716, 6.5621, 6.0976, 8.9491, 10.5537, 6.6961, 9.0845, 3.0358, 5.5621,
];
function combinePerp(acc, a, len) {
let avg = Math.log(acc);
let sum = avg * len;
sum += Math.log(a);
avg = sum / (len + 1);
return Math.exp(avg);
}
function chunksToRunningScores(chunks) {
let intermediatePerpScores = [chunks[0]];
for (let i = 1; i < chunks.length; ++i) {
intermediatePerpScores[i] = combinePerp(intermediatePerpScores[i - 1], chunks[i], i);
}
return intermediatePerpScores;
}
function fyShuffle(data) {
let out = [...data];
let i = out.length;
while (--i > 0) {
let idx = Math.floor(Math.random() * (i + 1));
[out[idx], out[i]] = [out[i], out[idx]];
}
return out;
}
let test_N = 20000;
let Ns = data.map(() => []);
for (let i = 0; i < test_N; ++i) {
let randomized = fyShuffle(data);
let running = chunksToRunningScores(randomized);
for (let N = 1; N < data.length; ++N) {
Ns[N].push(Math.abs(5.9565 - running[N]));
}
}
Ns.forEach(x => x.sort((a, b) => a - b));
let idx = Math.floor(.9 * test_N); // 90% CI
for (let N = 1; N < Ns.length; ++N) {
console.log(N, Ns[N][idx].toFixed(4));
} |

|
yes, and change filename to q4_1 , so you know :) |
|
@gjmulder can you chime in and tell us which 65B model you are testing right now? |
|
I am moving this to a Discussion. too much chatter in an merged pr :) edit: #406 |

|
Generating the new 65B q4_1 set now. Each file is 5.7GB rather than 4.8GB - I assume that is expected? 15G models/65B/ggml-model-f16.bin.1 |
@jasontitus - nice! to clarify though, the output is already averaged over the steps - so, the perplexity is 3.9331 averaged across the first 11 chunks at this point. |

yes, the quantization stores extra values, but produces better results. |

|
Great work! Evaluating q4_1 on an M1 Ultra might be a bit tough, since we don't have ARM NEON code for q4_1 inference yet (only AVX2 for Skylake-and-beyond Intel processors and compatible) and so it would fall back to the much, much slower scalar code. For those machines that do have AVX2, for Q4_1, I recommend pulling in code from my branch, which should run a little faster (5~10%in my tests). I've also been thinking if we shouldn't introduce a quantization format that matches GPTQ exactly, with a single shared scale and offset for each block. This has potential to be much more performant, as then the data fetched in each AVX2 accumulation step (16 bytes) could be perfectly cache-aligned, memory usage would be almost 1/3 lower, and inference is largely memory-bound anyway. (@ggerganov , what would be a good name for that format? |
|
|
|
I think I understand the GPTQ algorithm a bit better after reading the original paper (but it's not like I have the hardware to run it myself). Otherwise, your post in #397 actually subsumes most ideas I had - I was thinking it might be worth trying to do local gradient descent on the offset/range to minimize the squared error (equivalent to minimizing RMS, since sqrt is monotonic). The paper you linked is quite interesting too - I wonder if some of the simpler techniques mentioned in it/its references (such as picking the nth-percentile value rather than the max to determine the quantization range) are applicable in our case, since most of those tests seem to have been done with int8 but jointly quantizing a lot more values. I was testing the new perplexity measure with my performance fork and was dismayed to see deteriorations on the order of 0.05 for the score on the first batch (no time to run more) (when trying to measure the perplexity on various source files from HEAD). After permuting some more (commuting on \mathbb{R}) operations in the code (and, among others, getting a small improvement relative to baseline with one ordering), I'm pretty sure there are some numerical stability issues we're neglecting there. With my ~n=3 samples (main.cpp, utils.cpp, utils.h), the differences are always directionally the same (that is: variants that are bad on one are bad on all), which means some of them probably systematically result in more big+small additions. |


|
@blackhole89 It is worth running some number of those tests. It doesn't really mean much if the first batch inference is a bit worse or better, only the bigger average is important. While the first result should be composed of the logarithmic average of 256 inferences, it still has a lot of noise there. I am using the 3rd number output, and by that point tests run seems to be acting as expected, e.g. if I know RMS is reduced by a quantization I am trying, by that time the test results appear to get slightly better. This is all a bit preliminary, though. I have only had so much time to play with trying to improve the quantization, and my approach is currently quite boneheaded. I saw this link https://github.com/qwopqwop200/GPTQ-for-LLaMa with tables and they had round-to-nearest, which I take to be similar to Q4_1 judging from the result, though I don't know the details on what batching was used, for example. It had mere 6.28 perplexity result and GPTQ was only 6.26 for 7B model, barely better, with 128 element block size. This doesn't really fit, the other papers that have used round-to-nearest vs. GPTQ show improvement that approach quite close to ff16 baseline. |
|
@alankila I went and performed some tests on that (see this comment). Preliminarily, it seems to me that for quantizations and calculation tweaks to the same model, something like the first 30 batches is enough (though the <10 I did are indeed likely too few to detect improvements/deteriorations at the order of magnitude I see). However, comparing across models is much iffier (and in fact I get the sense that Wikitext itself is too short to really separate out quality differences at the scale we see: the last 5% of blocks produce unpredictable perplexity deviations of almost 0.1, so e.g. the "quality" ordering of two models with perplexity 5.1 and 5.3 resp. could be inverted by adding another 5% more text that's "like Wikitext"). |


"bot-in-a-box" - model d/l and automatic install into a OpenBLAS or CuBLAS Docker image

* Compute perplexity over prompt

* More accurate perplexity calculation - over all logits in the context window (so 512x more tokens!)

* Output all perplexitiies

* Add timing/ETA
* Compute perplexity over prompt

* More accurate perplexity calculation - over all logits in the context window (so 512x more tokens!)

* Output all perplexitiies

* Add timing/ETA


Co-authored-by: Iwan Kawrakow <iwan.kawrakow@gmail.com>
* Compute perplexity over prompt

* More accurate perplexity calculation - over all logits in the context window (so 512x more tokens!)

* Output all perplexitiies

* Add timing/ETA
* Compute perplexity over prompt

* More accurate perplexity calculation - over all logits in the context window (so 512x more tokens!)

* Output all perplexitiies

* Add timing/ETA


…dest

The do_reset search at prefill time uses 'cur.pos_min < pos_min_thold' to
find a checkpoint whose recurrent state covers the LCP-aligned position.
For hybrid models with bounded recurrence (Gated DeltaNet / Mamba), pos_min
is bounded by the rec window size, so checkpoints with recent pos_min never
satisfy the constraint for early-LCP future turns.

Evicting insertion-oldest (the previous behavior) loses mid-checkpoints
from long turns first when short follow-up turns add deferred finals to
the same ring. That leaves the slot with only recent deferred finals, all
with high pos_min, forcing do_reset to fire on every future turn whose
LCP predates the latest rec window.

Repro: long first turn (creates low-pos_min mid-checkpoints) followed by
many short turns (each adds a high-pos_min deferred final). The mid-
checkpoints get evicted first, so when an LCP-match turn comes along,
no checkpoint satisfies 'cur.pos_min < pos_min_thold', do_reset fires,
and n_past=0 forces a full reprocess of all prompt tokens. Observed on
task ggml-org#270: full reprocess of 28123 tokens.

Verified locally on Qwen3.6-27B (also a hybrid DeltaNet): 8-turn convo
with long first turn + 7 short follow-ups. With the fix, every turn
restores from a low-pos_min checkpoint and do_reset never fires.
Without the fix, do_reset fires on every short turn.

…dest

The do_reset search at prefill time uses 'cur.pos_min < pos_min_thold' to
find a checkpoint whose recurrent state covers the LCP-aligned position.
For hybrid models with bounded recurrence (Gated DeltaNet / Mamba), pos_min
is bounded by the rec window size, so checkpoints with recent pos_min never
satisfy the constraint for early-LCP future turns.

Evicting insertion-oldest (the previous behavior) loses mid-checkpoints
from long turns first when short follow-up turns add deferred finals to
the same ring. That leaves the slot with only recent deferred finals, all
with high pos_min, forcing do_reset to fire on every future turn whose
LCP predates the latest rec window.

Repro: long first turn (creates low-pos_min mid-checkpoints) followed by
many short turns (each adds a high-pos_min deferred final). The mid-
checkpoints get evicted first, so when an LCP-match turn comes along,
no checkpoint satisfies 'cur.pos_min < pos_min_thold', do_reset fires,
and n_past=0 forces a full reprocess of all prompt tokens. Observed on
task ggml-org#270: full reprocess of 28123 tokens.

Verified locally on Qwen3.6-27B (also a hybrid DeltaNet): 8-turn convo
with long first turn + 7 short follow-ups. With the fix, every turn
restores from a low-pos_min checkpoint and do_reset never fires.
Without the fix, do_reset fires on every short turn.
…dest

The do_reset search at prefill time uses 'cur.pos_min < pos_min_thold' to
find a checkpoint whose recurrent state covers the LCP-aligned position.
For hybrid models with bounded recurrence (Gated DeltaNet / Mamba), pos_min
is bounded by the rec window size, so checkpoints with recent pos_min never
satisfy the constraint for early-LCP future turns.

Evicting insertion-oldest (the previous behavior) loses mid-checkpoints
from long turns first when short follow-up turns add deferred finals to
the same ring. That leaves the slot with only recent deferred finals, all
with high pos_min, forcing do_reset to fire on every future turn whose
LCP predates the latest rec window.

Repro: long first turn (creates low-pos_min mid-checkpoints) followed by
many short turns (each adds a high-pos_min deferred final). The mid-
checkpoints get evicted first, so when an LCP-match turn comes along,
no checkpoint satisfies 'cur.pos_min < pos_min_thold', do_reset fires,
and n_past=0 forces a full reprocess of all prompt tokens. Observed on
task ggml-org#270: full reprocess of 28123 tokens.

Verified locally on Qwen3.6-27B (also a hybrid DeltaNet): 8-turn convo
with long first turn + 7 short follow-ups. With the fix, every turn
restores from a low-pos_min checkpoint and do_reset never fires.
Without the fix, do_reset fires on every short turn.

…dest

The do_reset search at prefill time uses 'cur.pos_min < pos_min_thold' to
find a checkpoint whose recurrent state covers the LCP-aligned position.
For hybrid models with bounded recurrence (Gated DeltaNet / Mamba), pos_min
is bounded by the rec window size, so checkpoints with recent pos_min never
satisfy the constraint for early-LCP future turns.

Evicting insertion-oldest (the previous behavior) loses mid-checkpoints
from long turns first when short follow-up turns add deferred finals to
the same ring. That leaves the slot with only recent deferred finals, all
with high pos_min, forcing do_reset to fire on every future turn whose
LCP predates the latest rec window.

Repro: long first turn (creates low-pos_min mid-checkpoints) followed by
many short turns (each adds a high-pos_min deferred final). The mid-
checkpoints get evicted first, so when an LCP-match turn comes along,
no checkpoint satisfies 'cur.pos_min < pos_min_thold', do_reset fires,
and n_past=0 forces a full reprocess of all prompt tokens. Observed on
task ggml-org#270: full reprocess of 28123 tokens.

Verified locally on Qwen3.6-27B (also a hybrid DeltaNet): 8-turn convo
with long first turn + 7 short follow-ups. With the fix, every turn
restores from a low-pos_min checkpoint and do_reset never fires.
Without the fix, do_reset fires on every short turn.
… derived kq mask

Band (RDNA4 WMMA GQA fold, wide verify band, GQA cap ggml-org#133, the
ggml_set_fa_tensor_parallel hint), native quantized q8_0/q4_0/q4_1/q5_0/q5_1/
iq4_nl/bf16 K/V reads, the V3 derived kq-mask inputs (cell_pos/tok_lo/tok_hi),
the iq4_nl FA quants and the per-type tile instances.

The per-context fattn_stage prefill arena (and its RDNA3_5 prefill band split)
is deferred to block 10 slab-moe: here a native-capable operand is read natively
at every width and the F16 staging copy for a non-native type goes to the node's
reserved scratch (the pre-arena behaviour).

Env-read hygiene (no behaviour change): resolve GGML_CUDA_FA_WMMA_256 / GGML_CUDA_FA_WMMA_MAX_HEAD
once into values rather than caching the getenv() pointer (unsafe on Windows).

RDNA2 (gfx1030) FA gate fixes, reported and validated by @slavap (PR ggml-org#181;
Radeon Pro V620 + RX 7900 XTX, ROCm 7.2.4, one gfx1030;gfx1100 build, the full
FLASH_ATTN_EXT and MUL_MAT backend-ops gates green on both cards).  Without them
the gfx1030 FLASH_ATTN_EXT gate aborted with "ROCm error: an illegal memory
access" and MUL_MAT was blocked behind it.  Three separate defects:

- ggml_cuda_flash_attn_ext_get_alloc_size (TILE branch): FATTN_KV_NATIVE_BF16
  is the *F16 staging* type on hardware without native BF16 tensor cores -- the
  tile case chooser only picks the BF16 instantiation under
  bf16_mma_hardware_available, and gfx1030 has no V_DOT2_F32_BF16 -- so mapping
  it to GGML_TYPE_BF16 left need_f16 false and let the whole-cache converter
  write past the node's allocation (sentinel clobber, then illegal access).
  The mapping now matches the chooser.  The same latent mismatch existed on
  RDNA1 and on pre-Ampere NVIDIA / older MUSA.
- launch_fattn_tile_switch_ncols1: the decode/verify band (Q->ne[1] <= 8) was
  the only one of the seven launch sites that omitted the q_h2 argument, so it
  defaulted to false while a wide RDNA2 kernel (q_global: GGML_CUDA_FATTN_TILE_
  Q_GLOBAL, DKQ <= 256, ncols >= 16) read Q from the Q_h2 global half2 buffer
  that was never allocated -- a null pointer and a fault near 0x1000 for GQA-16
  decode shapes (hsk=192, nr23=[16,1], n_q <= 8).  It now passes the same
  condition as the other six.
- ggml_cuda_flash_attn_ext_get_f16_extra_data: the ncols2 > 1 tile branch loads
  its KV tiles without out-of-bounds checks, so the last tile reads up to
  nbatch_fa - 1 rows past the operand.  The KV cache allocation has always had
  that slack, but the converted F16 scratch is exact size and sits at the end of
  the node's allocation, so it read into the next allocation.  A 511-row guard
  tail is now reserved after each converted operand (the nbatch_fa config field
  is 9 bits and the table asserts <= 256, so half is margin), gated on
  GGML_CUDA_CC_IS_RDNA2 so every other backend keeps its allocation sizes.

Fold (r92): the 2-byte band arm joins the 32-column band block, and the RDNA4
head-512 row goes back to upstream's shape.  (a) `ggml_cuda_fattn_band_wmma_ncols1()`
no longer special-cases f16/bf16 (native BF16) to 2 columns, and the 2-byte band split
drops from 3*nsm/4 to nsm/2.  The 2-column tile was the right default only while that arm
still selected the pre-band 128-half2 config row: with the band's own 64-half2 row it wins
~5 % at n_q = 1 and loses everywhere else, because ceil(n_q/2) output tiles each stream the
whole KV cache (head 256 GQA 6, gfx1201, us per call, f16 KV: n_q 1 760 -> 684, n_q 4
763 -> 695, n_q 8 1142 -> 823 at kv 98304; bf16 813/869/1451 -> 685/696/832).  The choice
stays width-independent, so W = 1..8 still reduce identically (GREEDY-PURITY.md §36).
(b) The `(512, 512, 32)` RDNA row -- the only head-512 row the AMD dispatcher can reach,
since `switch_ncols1` forces ncols = 32/ncols2 for DKQ > 256 -- was replaced by the
2026-09-14 RDNA prefill sweep with an 8-warp / 128-KV-row / nbatch_V2 16 config that is
~1.35x slower than the tile kernel, which made RDNA4's WMMA head cap of 576 a prefill
regression for every Gemma 4 global layer (issue ggml-org#188).  Retuned to 4 warps, 32 KV rows,
one 128-half2 K/V batch, combine 64, Q in registers: gemma-4 31B global-attn shape (D=512,
4 KV heads, 32 Q heads, ub 512, q8_0 KV) 32768 126.1 -> 42.3 ms and 98304 377.0 -> 128.1 ms,
end to end pp512 +95 % at d32768 and +144 % at d98304 (31B and 26B-A4B).  Records:
archive/work/fa-band-2byte-row/, upstream/UPSTREAM-PR-fa-512-rdna-head-cap/.

Fold (r98, PR ggml-org#195, @overdoingism): with q8_0 K and V read in place (decode/verify, up to 8 query rows)
the RDNA4 band launches a second kernel variant, `flash_attn_ext_f16<..., band_fetch_ahead = true>`, which
fetches the raw q8_0 bytes of the next K/V batches into registers ahead of use and converts a batch into
shared memory only when it is due; its barriers order shared memory only (release / s_barrier / acquire on
"local"), because `__syncthreads()` also waits for every outstanding global load and would drain the fetches
at the next barrier.  The quants stay packed in 32-bit words, with an empty `asm volatile` pinning the
conversion at the stage point (otherwise the compiler unpacks the bytes right after the fetch, which waits
there and needs 4x the registers).  64-column block (widths 5..8): two batches in flight, Q in registers.
32-column block (widths 1..4): one batch in flight and the stream continues across the iteration boundary
into the next KV block that is not fully masked, Q read from shared memory (a register-resident Q is spilled
there and its scratch reloads share the load counter with the fetched K/V).  The variant is compiled in two
generated translation units of its own (`template-instances/fattn-mma-f16-band-fetch-ahead-ncols1_{4,8}-
ncols2_8-dkq256-dv256.cu`, emitted by generate_cu_files.py), so every other launch, including f16 / bf16 K/V
and prefill, compiles to the same gfx1201 instructions as before it (verified at the assembly level: 0
differing instructions in both dkq256 band instances, a dkq128 instance, the tile and vec units and
fattn.cu).  Default on; `GGML_HIP_FA_BAND_FETCH_AHEAD=0` runs the kernel without it for q8_0 too.  It also
keys the FA shared-memory attribute raise per (variant, device) rather than per device, so the two kernels
cannot share one "already raised" flag.

Gates (gfx1201, ROCm 10.1.0, 27B UD-Q4_K_XL with q8_0 K/V unless noted): bit-identical to r97 everywhere
the variant fires -- `test-backend-ops -o FLASH_ATTN_EXT` 6391/6391 on both builds, prefill-logit KLD
0.000000 / same-top-p 100.000 %, greedy text identical at 8K and 110K context, on a 2 GPU tensor split and
on gemma4 12B (its head-256 SWA layers), the 4-axis adaptive MTP gate at -n 3000 (text and draft acceptance
identical on all four axes) and n7 = plain; `llama-batched-bench -npp 16 -ntg 32 -npl 1,4,8` B=1 29.47 ->
30.12 t/s, B=4 95.73 -> 97.70, B=8 flat; decode +0.7 % at 8K and +2.4 % at 110K context (3 interleaved pairs
each; prefill unchanged at 840 t/s), +0.9 % on the 2 GPU tensor split.

Fold (r99, PR ggml-org#198, @slavap): two RDNA2 (gfx1030) FA follow-ups from the review of PR ggml-org#181, plus the
arch-independent half they needed.

- **One tile K/V type selection.**  The tile kernel has a single K/V type parameter and its choice was kept
  by hand in two places: the instantiation (`ggml_cuda_flash_attn_ext_tile_case_type`, `fattn-tile.cu`) and
  the F16 scratch sizing (`ggml_cuda_flash_attn_ext_get_alloc_size`, `fattn.cu`).  They had drifted three
  times (the missing q4_0 arm, the mixed-K/V NaNs, the missing RDNA2 bf16 scratch).  Both now call one
  `ggml_cuda_fattn_tile_type(K, V, cc)` in `fattn-rdna.cuh`: BF16 only where the hardware reads it natively,
  else the native dequant type, else F16 (BF16 without native support maps to F16, i.e. the launcher
  converts).  The mapping is 1:1 with the previous order on every arch, the instantiation set is unchanged
  (96 tile objects before and after) and the host change leaves every tile kernel's gfx1201 ISA identical.
- **Checked tail for the last unchecked tile (RDNA2 only).**  The `ncols2 > 1` tile branch loads its KV
  tiles without out-of-bounds checks, so its last tile can read up to `nbatch_fa - 1` rows past the KV data.
  In a model that stays inside the KV cache tensor's slack, but an exact-size operand (test-backend-ops) can
  reach the neighbouring allocation.  On RDNA2 the last tile now takes the already-compiled
  `oob_check = true` form (zero-fills the tail and keeps it out of the softmax).  Every other target is
  untouched: `RDNA2` is defined only in the gfx103x device pass (`vendors/hip.h`), the added block is inside
  `#if defined(RDNA2)`, and the gfx1201 tile instances are byte-identical in ISA to r98.
- **The 511-row guard tail is kept** and its derivation documented: `nbatch_fa` is a 9-bit config field but
  `GGML_CUDA_FATTN_TILE_CONFIG_CASE` static_asserts `<= 256`, each K chunk loads `nbatch_fa` rows and each V
  chunk `nbatch_V` with `static_assert(nbatch_fa % nbatch_V == 0)`, so the over-read is at most `255` rows;
  511 = 2 x 256 - 1.  Since the RDNA2 tail is now checked, the tail is belt-and-braces, not the only
  protection.  Comment only: no allocation size changes on any backend.

Gates (gfx1201, ROCm 10.1.0): `test-backend-ops -o FLASH_ATTN_EXT` 6391/6391 (identical per case to r98),
prefill-logit KLD 0.000000 / 100.000 %, greedy text identical to r98, `validate-set.sh` green, per-block
build green.  A `gfx1201;gfx1030` dual-target build compiles the RDNA2 arm; the RDNA2 runtime gate is the
reporter's (Radeon Pro V620, ROCm 7.2.4: FLASH_ATTN_EXT 6389/6389, MUL_MAT 2444/2444 with the add-on, and
the same on gfx1100).

RDNA3_0 (gfx1100) head-512 WMMA prefill rows, reported by @briansp2020 (PR ggml-org#199;
RX 7900 XTX).  The RDNA head-512 rows were tuned on gfx1201 and keep Q in
registers, so on gfx1100 every head-512 kernel sat at the 256-VGPR limit and
spilled (~1.0-1.4k VGPRs per lane); head 512 was therefore capped back to the
tile kernel on RDNA3_0 in r5 (issue ggml-org#30).  RDNA3_0 now has its own rows for
DKQ == DV == 512 (Q in shared memory, 128 threads, 64-wide K/V/combine
batches), and head 512 takes WMMA prefill again on top of the 256 cap: other
heads above 256 keep the tile kernel, RDNA4/RDNA3_5 rows are unchanged and the
decode/verify band stays on the tile kernel.  GGML_CUDA_FA_RDNA3_WMMA_512=0
disables it; GGML_CUDA_FA_WMMA_256=0 and GGML_CUDA_FA_WMMA_MAX_HEAD still take
it out (the rows are RDNA3_0-only, so MAX_HEAD only decides whether head 512
takes WMMA at all).

Measured on gfx1100 (gemma-4-26B-A4B QAT UD-Q4_K_XL, q8_0 KV, pp2048):
d32768 1908.3/1909.2 -> 2549.1/2554.6 t/s (+34 %), d65536 1209.3/1207.6 ->
1756.2/1757.5 (+45 %), tg128 at d32768 unchanged (127.74/127.74 ->
127.80/127.73).  FLASH_ATTN_EXT 6391/6391 on gfx1100; the switch-off text is
bit-identical to r101 and gfx1201/gfx1151 output is unchanged (byte-identical on
gemma4-26B-A4B).

Prefill-logit NOTE (known limitation, TODO ggml-org#81 / wip/fa-rdna3-head512-purity):
this is a tile->WMMA family switch, so it moves the prefill logits against the
tile kernel: mean KLD 0.0293 / same-top-p 92.59 % on that model at the gate's
out-of-domain point (PPL 604), i.e. it does NOT meet the absolute 0.005 / 98 %
gate.  Calibrated at the same point: the head-256 WMMA rows the delivery has
shipped default-on for gfx1100 since r5 measure 0.0441 / 90.63 %, a benign
ubatch change on the same kernel ~0.12 per chunk, and the issue-ggml-org#113 BF16
chunked GDN 0.62.  PPL is unchanged within its +/-5 % error bar (f16 KV 604.06
vs 607.20, q8_0 KV 617.85 vs 620.59).  Accepted as no worse than the shipped
equivalent switch; the campaign above exists to close the gap.

kq-mask fill guards, reported, root-caused and validated by @RikshaDriver (PR ggml-org#222,
issue ggml-org#221; RX 7600 gfx1102, ROCm 10.1, bailingmoe3 / Ling-3.0-tiny-IQ4_NL).  Only a
single-sequence context enables the derived kq form, so the packed mask in
llm_graph_input_mem_hybrid_k is left with no consumer, the allocator gives an
unconsumed input no buffer, and the unconditional fill asserted on it
(GGML_ASSERT(buffer) via llama_kv_cache::set_input_kq_mask) - llama-cli aborted
before the first token.  Ten of the thirteen fill sites in src/llama-graph.cpp
already guard for exactly that; llm_graph_input_mem_hybrid_k and
llm_graph_input_attn_k_dsa (its mla and lid masks) now carry the same guard as
their siblings.  can_reuse needs nothing: can_reuse_kq_mask() reads ne[] only.

The decode/verify band's fully-masked KV group skip, reported by @overdoingism
(PR ggml-org#223, the same reporter whose issue ggml-org#45 the band came from).  The prefill
skip built its packed bitmap under Q->ne[1] > 8, so the band read every other
slot's -INF cells on every decode step - the cost LLAMA_SERVER_LAZY_IDLE_SLOTS
(r130) made common.  The band now gets the bitmap too and its loop, which
already handled it (and had never been reached), skips the fully masked
iterations while keeping its round-robin split: block i still owns i, i+P, ...,
so the accumulation order over the rest is unchanged and the result is
bit-identical.  GGML_CUDA_FA_BAND_SKIP=0 (band arm) / GGML_CUDA_FA_MASK_SKIP=0
(the whole mechanism) turn it off.  Measured gfx1201, 27B UD-Q4_K_XL, 2 slots
unified, q8_0 KV: a resident ~105K conversation behind an active 9.8K one
50.84 -> 41.69 ms/step (-18 %, token ids identical; with a DFlash2 draft at
n-max 5: 18.62 -> 14.83), -0.6 % with nothing to skip.  The delivery adds the
decode-width packed-hole op cases (the band skip had no oracle) and evaluates
the band predicate once for both the skip gate and the 2-D launch.

Co-authored-by: overdoingism <overdoingism@users.noreply.github.com>

Fold (r134, issue ggml-org#224): the band's 64-column block (query widths 5..8) gets its own
geometry and its own instantiation.  A band block's per-column reduction splits the KV
rows of a tile nwarps*cols_per_warp/ncols (np) ways, and that split is part of the width
purity contract: the 32-column block (widths 1..4, 8 warps, np 4) and the 64-column block
must split them identically, or greedy decode with a draft differs from decode without
one.  r126 removed the 16-warp row for ncols 64 (it was also the prefill instantiation),
which left widths 5..8 on prefill's 8-warp table row (np 2) -- a reordered reduction,
~1e-3 relative, invisible to every throughput number, same-seed text gate and
CPU-referenced op test, and reported as an 8K/110K greedy divergence on dense head-256
GQA-6 (Qwen3.8-27B + DFlash2, plain != draft on r131, identical with
GGML_HIP_FA_BAND_WIDE=0 and on r123).  The 16-warp band row is back
(fattn_mma_config(512, 1, 64, 64, 64, 32, 1, true), nbatch_combine 32 to stay inside the
64 KiB LDS limit at 16 warps), selected by a new compile-time `band_wide` flag threaded
through the config getters, the case function and the kernel, so prefill keeps the
256-thread table row and its deep-prefill win (pp512 @ d98304 unchanged).  The band's
64-column case + its q8_0 fetch-ahead variant are separate translation units
(template-instances/fattn-mma-f16-band-wide-*.cu, emitted by generate_cu_files.py).
A static_assert on the two band rows (np and the KV batch shape must match) makes this
class of regression a build error.

Fold (r164, PR ggml-org#242, overdoingism): `llm_graph_input_kq_derived::can_reuse()` looks through a
`llama_memory_hybrid_context` to its attention cache.  A hybrid model's `params.mctx` is the wrapper, never the
`llama_kv_cache_context` the input was built from, so the derived input rejected reuse for *every*
single-sequence batch of more than 8 tokens - and since `LLAMA_KV_N_PAD_MIN` holds `n_kv` on the 256-cell
stride the derived form's own gate requires, those batches really did take the derived form, so each one
rebuilt its graph: a 9-16 row n-gram verification step, or an MTP verify step at
`--spec-draft-n-max >= 8` (0 graphs reused over 300 decode tokens at a fixed depth 15, i.e. 6820 -> 6338 ms
on 3 GPU `-sm tensor` and 5329 -> 5041 ms at 2 GPU, +7.6 % / +5.7 % - against this block's own
`LLAMA_KQ_MASK_DERIVED=0`).  `get_attn()` is exactly the cache `build_inp_mem_hybrid()` built the input from,
and the existing checks (n_kv, stream count, token count, `kq_mask_derivable()`) then run against it
unchanged, so reuse returns to parity with the packed path (n-gram n_max 15 on 1 GPU: 58 -> 77 reused =
the packed arm; 3 GPU: 0 -> 97) with greedy text and draft acceptance byte-identical on every arm.  iSWA
still rejects, necessarily: `build_inp_mem_hybrid_iswa()` creates *two* derived inputs (one bound to the base
cache, one to the SWA cache), so there is no single cache to look through.  `LLAMA_KQ_MASK_DERIVED_REUSE=0`
restores the rejection.

Fold (r172, PR ggml-org#247, overdoingism): the derived kq mask covers batches of several sequences, so a
`--parallel > 1 --kv-unified` context stops reserving the packed mask (n_kv x n_ubatch x 2 bytes on each
device and again pinned on the host).  Sequence k of the ubatch has its cells and its tokens' [lo, hi]
shifted by k * 2^23 (KQ_DERIVED_SEQ_STRIDE), so the existing `tok_lo <= cell_pos <= tok_hi` predicate
keeps every token inside its own sequence's range and the FA kernels need no change.  The form is taken
only when one KV stream holds the batch, every token is in exactly one sequence, no cell carries two of
the batch's sequences (`llama_kv_cells` now counts those, so the check is O(1) unless
`llama_memory_seq_cp` was used) and every position is below the stride; a multi-sequence batch of at most
32 tokens (the multi-slot verify steps) and every other refused shape keeps the packed mask.
`kq_mask_packed_reachable()` drops its `n_seq_max > 1` term, and `decode()` latches
`kq_mask_multiseq_seen` on the first pre-split batch the form cannot serve and re-reserves once with the
packed mask (the r160 2-D latch pattern, so no later batch grows the compute buffer - issue ggml-org#42).
Measured (gfx1201, dense 27B UD-Q4_K_XL, `-c 245760 -ub 2048 --parallel 2 --kv-unified -ctk/-ctv q8_0`):
device memory 27.51 -> 26.41 GB and server RSS 1.97 -> 0.98 GiB after load, two concurrent 16K prefills
unchanged (26.96 vs 27.23 s at 1 GPU; 17.07 vs 17.09 s at 2 GPU `-sm tensor`), single-sequence greedy text
byte-identical (dense / 35B-A3B MoE / hybrid 4B) and `plain == draft-mtp` identical.
Purity: the derived predicate *is* the packed one - the author's host oracle compares the two fills cell
by cell, re-run here with 0 mismatches on llama-perplexity at 4 sequences per ubatch (dense 27B at 1 and
2 GPU tensor, Qwen3.5-4B hybrid, Gemma4-12B and gpt-oss-20b iSWA) and on the 2-slot server shape; the
prefill-logit gate at `--ub 2048 --ab "LLAMA_KQ_MASK_DERIVED_MULTISEQ=0"` reads 0.000000 / 100.000 % at
both f16 and q8_0 KV, and `gate-park-idle-slots.sh` passes at 3 GPU tensor.  No effect on a graph that
also holds an `allow_derived = false` builder (qwen4exp/QSA, MLA): its packed mask is created and filled
anyway - measured identical VRAM and RSS on Flash-Next.  `LLAMA_KQ_MASK_DERIVED_MULTISEQ=0` restores the
single-sequence rule and the packed reserve.

Fold (r208): RDNA2 (gfx1030) FA prefill, reported and validated by @slavap (PR ggml-org#270/ggml-org#271;
Radeon Pro V620 gfx1030, Qwen3.6-35B-A3B IQ4_XS, -b 8192 -ub 2048 -fa 1).  This is the RDNA2
long-context deficit of issue ggml-org#214, and it is folded here rather than cut as new blocks.

- q_global threshold 16 -> 64: the two kernel-side conditions, the Q_tmp_count stub and all
  seven launcher q_h2 arguments move together (a launcher that omits the argument is the r88
  null-Q_h2 fault).  At ncols 16..32 the global-half2 Q path re-reads Q per K-tile pass and
  the checked tail spilled ~180 VGPRs; with Q back in LDS it does not.
- rdna_cap_ncols2 lifted for DKQ == 256 (D=128 keeps the cap).  The cap dates from r76, when
  HIP's RDNA2 occupancy query returned 0 for the wide D=256 variants; launch_fattn computes
  RDNA2 occupancy itself now, so the cap is stale.  Checked against the tree's own formula
  (4*waves_per_simd/waves_per_block, LDS cap 128K/lds) over the patched gfx1030 HSACO: every
  D=256 shape the launcher can now pick reports >= 2 blocks, so the
  GGML_ASSERT(max_blocks_per_sm > 0) abort the cap guarded against is unreachable.
- the checked tail clamps out-of-range rows to the last in-bounds row instead of branching to
  a local zero array.  The tail values are discarded by the k_VKQ_sup guards, every read stays
  inside the cache, and the pointer-select the branch existed to avoid (the kv=113
  flat-scratch fault) is gone with it.  i_sup - 1 may be -1 (a V chunk wholly past the KV
  end): row -1 is the last VALID row, and every weight in that chunk is zero, so the comment
  in the loader says so and warns against "fixing" it to max(i_sup - 1, 0), which would read
  one row past the cache.

Verified here on ROCm 10.1.0 against this tree: both levers compile for gfx1030 (all 12
template-instances tile TUs, no warnings), the D=256 4x8/16x2 checked-tail scratch goes
480/500 B -> 0 B (the submitter's 488/520 on their toolchain), the largest static LDS in the
whole tile family stays 63488 B of gfx1030's 65536 B, and for gfx1201 every tile kernel's
machine code is bit-identical before and after (88/88 and 106/106 kernels hashed per kernel),
so RDNA4, RDNA3_0, RDNA3_5, NVIDIA and MUSA/SYCL keep their codegen and numerics exactly.
The timings stay the submitter's (pp2048 @ d32768 1041.0 -> 1259.8 t/s, tg256 @ d131072
50.9 -> 62.4 across their two arms); RDNA2 is best-effort per CONTAINERS.md and carries no
gate in this repo.

Not taken from the PRs: their own patches-rdna2-r205/ + release-rdna2-r205.json +
scripts/apply-rdna2-r205.sh re-packaging (the same call as r88), and the block 16 two-lane
prefill the branches were stacked on (PR ggml-org#268, a separate candidate).
… derived kq mask

Band (RDNA4 WMMA GQA fold, wide verify band, GQA cap ggml-org#133, the
ggml_set_fa_tensor_parallel hint), native quantized q8_0/q4_0/q4_1/q5_0/q5_1/
iq4_nl/bf16 K/V reads, the V3 derived kq-mask inputs (cell_pos/tok_lo/tok_hi),
the iq4_nl FA quants and the per-type tile instances.

The per-context fattn_stage prefill arena (and its RDNA3_5 prefill band split)
is deferred to block 10 slab-moe: here a native-capable operand is read natively
at every width and the F16 staging copy for a non-native type goes to the node's
reserved scratch (the pre-arena behaviour).

Env-read hygiene (no behaviour change): resolve GGML_CUDA_FA_WMMA_256 / GGML_CUDA_FA_WMMA_MAX_HEAD
once into values rather than caching the getenv() pointer (unsafe on Windows).

RDNA2 (gfx1030) FA gate fixes, reported and validated by @slavap (PR ggml-org#181;
Radeon Pro V620 + RX 7900 XTX, ROCm 7.2.4, one gfx1030;gfx1100 build, the full
FLASH_ATTN_EXT and MUL_MAT backend-ops gates green on both cards).  Without them
the gfx1030 FLASH_ATTN_EXT gate aborted with "ROCm error: an illegal memory
access" and MUL_MAT was blocked behind it.  Three separate defects:

- ggml_cuda_flash_attn_ext_get_alloc_size (TILE branch): FATTN_KV_NATIVE_BF16
  is the *F16 staging* type on hardware without native BF16 tensor cores -- the
  tile case chooser only picks the BF16 instantiation under
  bf16_mma_hardware_available, and gfx1030 has no V_DOT2_F32_BF16 -- so mapping
  it to GGML_TYPE_BF16 left need_f16 false and let the whole-cache converter
  write past the node's allocation (sentinel clobber, then illegal access).
  The mapping now matches the chooser.  The same latent mismatch existed on
  RDNA1 and on pre-Ampere NVIDIA / older MUSA.
- launch_fattn_tile_switch_ncols1: the decode/verify band (Q->ne[1] <= 8) was
  the only one of the seven launch sites that omitted the q_h2 argument, so it
  defaulted to false while a wide RDNA2 kernel (q_global: GGML_CUDA_FATTN_TILE_
  Q_GLOBAL, DKQ <= 256, ncols >= 16) read Q from the Q_h2 global half2 buffer
  that was never allocated -- a null pointer and a fault near 0x1000 for GQA-16
  decode shapes (hsk=192, nr23=[16,1], n_q <= 8).  It now passes the same
  condition as the other six.
- ggml_cuda_flash_attn_ext_get_f16_extra_data: the ncols2 > 1 tile branch loads
  its KV tiles without out-of-bounds checks, so the last tile reads up to
  nbatch_fa - 1 rows past the operand.  The KV cache allocation has always had
  that slack, but the converted F16 scratch is exact size and sits at the end of
  the node's allocation, so it read into the next allocation.  A 511-row guard
  tail is now reserved after each converted operand (the nbatch_fa config field
  is 9 bits and the table asserts <= 256, so half is margin), gated on
  GGML_CUDA_CC_IS_RDNA2 so every other backend keeps its allocation sizes.

Fold (r92): the 2-byte band arm joins the 32-column band block, and the RDNA4
head-512 row goes back to upstream's shape.  (a) `ggml_cuda_fattn_band_wmma_ncols1()`
no longer special-cases f16/bf16 (native BF16) to 2 columns, and the 2-byte band split
drops from 3*nsm/4 to nsm/2.  The 2-column tile was the right default only while that arm
still selected the pre-band 128-half2 config row: with the band's own 64-half2 row it wins
~5 % at n_q = 1 and loses everywhere else, because ceil(n_q/2) output tiles each stream the
whole KV cache (head 256 GQA 6, gfx1201, us per call, f16 KV: n_q 1 760 -> 684, n_q 4
763 -> 695, n_q 8 1142 -> 823 at kv 98304; bf16 813/869/1451 -> 685/696/832).  The choice
stays width-independent, so W = 1..8 still reduce identically (GREEDY-PURITY.md §36).
(b) The `(512, 512, 32)` RDNA row -- the only head-512 row the AMD dispatcher can reach,
since `switch_ncols1` forces ncols = 32/ncols2 for DKQ > 256 -- was replaced by the
2026-09-14 RDNA prefill sweep with an 8-warp / 128-KV-row / nbatch_V2 16 config that is
~1.35x slower than the tile kernel, which made RDNA4's WMMA head cap of 576 a prefill
regression for every Gemma 4 global layer (issue ggml-org#188).  Retuned to 4 warps, 32 KV rows,
one 128-half2 K/V batch, combine 64, Q in registers: gemma-4 31B global-attn shape (D=512,
4 KV heads, 32 Q heads, ub 512, q8_0 KV) 32768 126.1 -> 42.3 ms and 98304 377.0 -> 128.1 ms,
end to end pp512 +95 % at d32768 and +144 % at d98304 (31B and 26B-A4B).  Records:
archive/work/fa-band-2byte-row/, upstream/UPSTREAM-PR-fa-512-rdna-head-cap/.

Fold (r98, PR ggml-org#195, @overdoingism): with q8_0 K and V read in place (decode/verify, up to 8 query rows)
the RDNA4 band launches a second kernel variant, `flash_attn_ext_f16<..., band_fetch_ahead = true>`, which
fetches the raw q8_0 bytes of the next K/V batches into registers ahead of use and converts a batch into
shared memory only when it is due; its barriers order shared memory only (release / s_barrier / acquire on
"local"), because `__syncthreads()` also waits for every outstanding global load and would drain the fetches
at the next barrier.  The quants stay packed in 32-bit words, with an empty `asm volatile` pinning the
conversion at the stage point (otherwise the compiler unpacks the bytes right after the fetch, which waits
there and needs 4x the registers).  64-column block (widths 5..8): two batches in flight, Q in registers.
32-column block (widths 1..4): one batch in flight and the stream continues across the iteration boundary
into the next KV block that is not fully masked, Q read from shared memory (a register-resident Q is spilled
there and its scratch reloads share the load counter with the fetched K/V).  The variant is compiled in two
generated translation units of its own (`template-instances/fattn-mma-f16-band-fetch-ahead-ncols1_{4,8}-
ncols2_8-dkq256-dv256.cu`, emitted by generate_cu_files.py), so every other launch, including f16 / bf16 K/V
and prefill, compiles to the same gfx1201 instructions as before it (verified at the assembly level: 0
differing instructions in both dkq256 band instances, a dkq128 instance, the tile and vec units and
fattn.cu).  Default on; `GGML_HIP_FA_BAND_FETCH_AHEAD=0` runs the kernel without it for q8_0 too.  It also
keys the FA shared-memory attribute raise per (variant, device) rather than per device, so the two kernels
cannot share one "already raised" flag.

Gates (gfx1201, ROCm 10.1.0, 27B UD-Q4_K_XL with q8_0 K/V unless noted): bit-identical to r97 everywhere
the variant fires -- `test-backend-ops -o FLASH_ATTN_EXT` 6391/6391 on both builds, prefill-logit KLD
0.000000 / same-top-p 100.000 %, greedy text identical at 8K and 110K context, on a 2 GPU tensor split and
on gemma4 12B (its head-256 SWA layers), the 4-axis adaptive MTP gate at -n 3000 (text and draft acceptance
identical on all four axes) and n7 = plain; `llama-batched-bench -npp 16 -ntg 32 -npl 1,4,8` B=1 29.47 ->
30.12 t/s, B=4 95.73 -> 97.70, B=8 flat; decode +0.7 % at 8K and +2.4 % at 110K context (3 interleaved pairs
each; prefill unchanged at 840 t/s), +0.9 % on the 2 GPU tensor split.

Fold (r99, PR ggml-org#198, @slavap): two RDNA2 (gfx1030) FA follow-ups from the review of PR ggml-org#181, plus the
arch-independent half they needed.

- **One tile K/V type selection.**  The tile kernel has a single K/V type parameter and its choice was kept
  by hand in two places: the instantiation (`ggml_cuda_flash_attn_ext_tile_case_type`, `fattn-tile.cu`) and
  the F16 scratch sizing (`ggml_cuda_flash_attn_ext_get_alloc_size`, `fattn.cu`).  They had drifted three
  times (the missing q4_0 arm, the mixed-K/V NaNs, the missing RDNA2 bf16 scratch).  Both now call one
  `ggml_cuda_fattn_tile_type(K, V, cc)` in `fattn-rdna.cuh`: BF16 only where the hardware reads it natively,
  else the native dequant type, else F16 (BF16 without native support maps to F16, i.e. the launcher
  converts).  The mapping is 1:1 with the previous order on every arch, the instantiation set is unchanged
  (96 tile objects before and after) and the host change leaves every tile kernel's gfx1201 ISA identical.
- **Checked tail for the last unchecked tile (RDNA2 only).**  The `ncols2 > 1` tile branch loads its KV
  tiles without out-of-bounds checks, so its last tile can read up to `nbatch_fa - 1` rows past the KV data.
  In a model that stays inside the KV cache tensor's slack, but an exact-size operand (test-backend-ops) can
  reach the neighbouring allocation.  On RDNA2 the last tile now takes the already-compiled
  `oob_check = true` form (zero-fills the tail and keeps it out of the softmax).  Every other target is
  untouched: `RDNA2` is defined only in the gfx103x device pass (`vendors/hip.h`), the added block is inside
  `#if defined(RDNA2)`, and the gfx1201 tile instances are byte-identical in ISA to r98.
- **The 511-row guard tail is kept** and its derivation documented: `nbatch_fa` is a 9-bit config field but
  `GGML_CUDA_FATTN_TILE_CONFIG_CASE` static_asserts `<= 256`, each K chunk loads `nbatch_fa` rows and each V
  chunk `nbatch_V` with `static_assert(nbatch_fa % nbatch_V == 0)`, so the over-read is at most `255` rows;
  511 = 2 x 256 - 1.  Since the RDNA2 tail is now checked, the tail is belt-and-braces, not the only
  protection.  Comment only: no allocation size changes on any backend.

Gates (gfx1201, ROCm 10.1.0): `test-backend-ops -o FLASH_ATTN_EXT` 6391/6391 (identical per case to r98),
prefill-logit KLD 0.000000 / 100.000 %, greedy text identical to r98, `validate-set.sh` green, per-block
build green.  A `gfx1201;gfx1030` dual-target build compiles the RDNA2 arm; the RDNA2 runtime gate is the
reporter's (Radeon Pro V620, ROCm 7.2.4: FLASH_ATTN_EXT 6389/6389, MUL_MAT 2444/2444 with the add-on, and
the same on gfx1100).

RDNA3_0 (gfx1100) head-512 WMMA prefill rows, reported by @briansp2020 (PR ggml-org#199;
RX 7900 XTX).  The RDNA head-512 rows were tuned on gfx1201 and keep Q in
registers, so on gfx1100 every head-512 kernel sat at the 256-VGPR limit and
spilled (~1.0-1.4k VGPRs per lane); head 512 was therefore capped back to the
tile kernel on RDNA3_0 in r5 (issue ggml-org#30).  RDNA3_0 now has its own rows for
DKQ == DV == 512 (Q in shared memory, 128 threads, 64-wide K/V/combine
batches), and head 512 takes WMMA prefill again on top of the 256 cap: other
heads above 256 keep the tile kernel, RDNA4/RDNA3_5 rows are unchanged and the
decode/verify band stays on the tile kernel.  GGML_CUDA_FA_RDNA3_WMMA_512=0
disables it; GGML_CUDA_FA_WMMA_256=0 and GGML_CUDA_FA_WMMA_MAX_HEAD still take
it out (the rows are RDNA3_0-only, so MAX_HEAD only decides whether head 512
takes WMMA at all).

Measured on gfx1100 (gemma-4-26B-A4B QAT UD-Q4_K_XL, q8_0 KV, pp2048):
d32768 1908.3/1909.2 -> 2549.1/2554.6 t/s (+34 %), d65536 1209.3/1207.6 ->
1756.2/1757.5 (+45 %), tg128 at d32768 unchanged (127.74/127.74 ->
127.80/127.73).  FLASH_ATTN_EXT 6391/6391 on gfx1100; the switch-off text is
bit-identical to r101 and gfx1201/gfx1151 output is unchanged (byte-identical on
gemma4-26B-A4B).

Prefill-logit NOTE (known limitation, TODO ggml-org#81 / wip/fa-rdna3-head512-purity):
this is a tile->WMMA family switch, so it moves the prefill logits against the
tile kernel: mean KLD 0.0293 / same-top-p 92.59 % on that model at the gate's
out-of-domain point (PPL 604), i.e. it does NOT meet the absolute 0.005 / 98 %
gate.  Calibrated at the same point: the head-256 WMMA rows the delivery has
shipped default-on for gfx1100 since r5 measure 0.0441 / 90.63 %, a benign
ubatch change on the same kernel ~0.12 per chunk, and the issue-ggml-org#113 BF16
chunked GDN 0.62.  PPL is unchanged within its +/-5 % error bar (f16 KV 604.06
vs 607.20, q8_0 KV 617.85 vs 620.59).  Accepted as no worse than the shipped
equivalent switch; the campaign above exists to close the gap.

kq-mask fill guards, reported, root-caused and validated by @RikshaDriver (PR ggml-org#222,
issue ggml-org#221; RX 7600 gfx1102, ROCm 10.1, bailingmoe3 / Ling-3.0-tiny-IQ4_NL).  Only a
single-sequence context enables the derived kq form, so the packed mask in
llm_graph_input_mem_hybrid_k is left with no consumer, the allocator gives an
unconsumed input no buffer, and the unconditional fill asserted on it
(GGML_ASSERT(buffer) via llama_kv_cache::set_input_kq_mask) - llama-cli aborted
before the first token.  Ten of the thirteen fill sites in src/llama-graph.cpp
already guard for exactly that; llm_graph_input_mem_hybrid_k and
llm_graph_input_attn_k_dsa (its mla and lid masks) now carry the same guard as
their siblings.  can_reuse needs nothing: can_reuse_kq_mask() reads ne[] only.

The decode/verify band's fully-masked KV group skip, reported by @overdoingism
(PR ggml-org#223, the same reporter whose issue ggml-org#45 the band came from).  The prefill
skip built its packed bitmap under Q->ne[1] > 8, so the band read every other
slot's -INF cells on every decode step - the cost LLAMA_SERVER_LAZY_IDLE_SLOTS
(r130) made common.  The band now gets the bitmap too and its loop, which
already handled it (and had never been reached), skips the fully masked
iterations while keeping its round-robin split: block i still owns i, i+P, ...,
so the accumulation order over the rest is unchanged and the result is
bit-identical.  GGML_CUDA_FA_BAND_SKIP=0 (band arm) / GGML_CUDA_FA_MASK_SKIP=0
(the whole mechanism) turn it off.  Measured gfx1201, 27B UD-Q4_K_XL, 2 slots
unified, q8_0 KV: a resident ~105K conversation behind an active 9.8K one
50.84 -> 41.69 ms/step (-18 %, token ids identical; with a DFlash2 draft at
n-max 5: 18.62 -> 14.83), -0.6 % with nothing to skip.  The delivery adds the
decode-width packed-hole op cases (the band skip had no oracle) and evaluates
the band predicate once for both the skip gate and the 2-D launch.

Co-authored-by: overdoingism <overdoingism@users.noreply.github.com>

Fold (r134, issue ggml-org#224): the band's 64-column block (query widths 5..8) gets its own
geometry and its own instantiation.  A band block's per-column reduction splits the KV
rows of a tile nwarps*cols_per_warp/ncols (np) ways, and that split is part of the width
purity contract: the 32-column block (widths 1..4, 8 warps, np 4) and the 64-column block
must split them identically, or greedy decode with a draft differs from decode without
one.  r126 removed the 16-warp row for ncols 64 (it was also the prefill instantiation),
which left widths 5..8 on prefill's 8-warp table row (np 2) -- a reordered reduction,
~1e-3 relative, invisible to every throughput number, same-seed text gate and
CPU-referenced op test, and reported as an 8K/110K greedy divergence on dense head-256
GQA-6 (Qwen3.8-27B + DFlash2, plain != draft on r131, identical with
GGML_HIP_FA_BAND_WIDE=0 and on r123).  The 16-warp band row is back
(fattn_mma_config(512, 1, 64, 64, 64, 32, 1, true), nbatch_combine 32 to stay inside the
64 KiB LDS limit at 16 warps), selected by a new compile-time `band_wide` flag threaded
through the config getters, the case function and the kernel, so prefill keeps the
256-thread table row and its deep-prefill win (pp512 @ d98304 unchanged).  The band's
64-column case + its q8_0 fetch-ahead variant are separate translation units
(template-instances/fattn-mma-f16-band-wide-*.cu, emitted by generate_cu_files.py).
A static_assert on the two band rows (np and the KV batch shape must match) makes this
class of regression a build error.

Fold (r164, PR ggml-org#242, overdoingism): `llm_graph_input_kq_derived::can_reuse()` looks through a
`llama_memory_hybrid_context` to its attention cache.  A hybrid model's `params.mctx` is the wrapper, never the
`llama_kv_cache_context` the input was built from, so the derived input rejected reuse for *every*
single-sequence batch of more than 8 tokens - and since `LLAMA_KV_N_PAD_MIN` holds `n_kv` on the 256-cell
stride the derived form's own gate requires, those batches really did take the derived form, so each one
rebuilt its graph: a 9-16 row n-gram verification step, or an MTP verify step at
`--spec-draft-n-max >= 8` (0 graphs reused over 300 decode tokens at a fixed depth 15, i.e. 6820 -> 6338 ms
on 3 GPU `-sm tensor` and 5329 -> 5041 ms at 2 GPU, +7.6 % / +5.7 % - against this block's own
`LLAMA_KQ_MASK_DERIVED=0`).  `get_attn()` is exactly the cache `build_inp_mem_hybrid()` built the input from,
and the existing checks (n_kv, stream count, token count, `kq_mask_derivable()`) then run against it
unchanged, so reuse returns to parity with the packed path (n-gram n_max 15 on 1 GPU: 58 -> 77 reused =
the packed arm; 3 GPU: 0 -> 97) with greedy text and draft acceptance byte-identical on every arm.  iSWA
still rejects, necessarily: `build_inp_mem_hybrid_iswa()` creates *two* derived inputs (one bound to the base
cache, one to the SWA cache), so there is no single cache to look through.  `LLAMA_KQ_MASK_DERIVED_REUSE=0`
restores the rejection.

Fold (r172, PR ggml-org#247, overdoingism): the derived kq mask covers batches of several sequences, so a
`--parallel > 1 --kv-unified` context stops reserving the packed mask (n_kv x n_ubatch x 2 bytes on each
device and again pinned on the host).  Sequence k of the ubatch has its cells and its tokens' [lo, hi]
shifted by k * 2^23 (KQ_DERIVED_SEQ_STRIDE), so the existing `tok_lo <= cell_pos <= tok_hi` predicate
keeps every token inside its own sequence's range and the FA kernels need no change.  The form is taken
only when one KV stream holds the batch, every token is in exactly one sequence, no cell carries two of
the batch's sequences (`llama_kv_cells` now counts those, so the check is O(1) unless
`llama_memory_seq_cp` was used) and every position is below the stride; a multi-sequence batch of at most
32 tokens (the multi-slot verify steps) and every other refused shape keeps the packed mask.
`kq_mask_packed_reachable()` drops its `n_seq_max > 1` term, and `decode()` latches
`kq_mask_multiseq_seen` on the first pre-split batch the form cannot serve and re-reserves once with the
packed mask (the r160 2-D latch pattern, so no later batch grows the compute buffer - issue ggml-org#42).
Measured (gfx1201, dense 27B UD-Q4_K_XL, `-c 245760 -ub 2048 --parallel 2 --kv-unified -ctk/-ctv q8_0`):
device memory 27.51 -> 26.41 GB and server RSS 1.97 -> 0.98 GiB after load, two concurrent 16K prefills
unchanged (26.96 vs 27.23 s at 1 GPU; 17.07 vs 17.09 s at 2 GPU `-sm tensor`), single-sequence greedy text
byte-identical (dense / 35B-A3B MoE / hybrid 4B) and `plain == draft-mtp` identical.
Purity: the derived predicate *is* the packed one - the author's host oracle compares the two fills cell
by cell, re-run here with 0 mismatches on llama-perplexity at 4 sequences per ubatch (dense 27B at 1 and
2 GPU tensor, Qwen3.5-4B hybrid, Gemma4-12B and gpt-oss-20b iSWA) and on the 2-slot server shape; the
prefill-logit gate at `--ub 2048 --ab "LLAMA_KQ_MASK_DERIVED_MULTISEQ=0"` reads 0.000000 / 100.000 % at
both f16 and q8_0 KV, and `gate-park-idle-slots.sh` passes at 3 GPU tensor.  No effect on a graph that
also holds an `allow_derived = false` builder (qwen4exp/QSA, MLA): its packed mask is created and filled
anyway - measured identical VRAM and RSS on Flash-Next.  `LLAMA_KQ_MASK_DERIVED_MULTISEQ=0` restores the
single-sequence rule and the packed reserve.

Fold (r208): RDNA2 (gfx1030) FA prefill, reported and validated by @slavap (PR ggml-org#270/ggml-org#271;
Radeon Pro V620 gfx1030, Qwen3.6-35B-A3B IQ4_XS, -b 8192 -ub 2048 -fa 1).  This is the RDNA2
long-context deficit of issue ggml-org#214, and it is folded here rather than cut as new blocks.

- q_global threshold 16 -> 64: the two kernel-side conditions, the Q_tmp_count stub and all
  seven launcher q_h2 arguments move together (a launcher that omits the argument is the r88
  null-Q_h2 fault).  At ncols 16..32 the global-half2 Q path re-reads Q per K-tile pass and
  the checked tail spilled ~180 VGPRs; with Q back in LDS it does not.
- rdna_cap_ncols2 lifted for DKQ == 256 (D=128 keeps the cap).  The cap dates from r76, when
  HIP's RDNA2 occupancy query returned 0 for the wide D=256 variants; launch_fattn computes
  RDNA2 occupancy itself now, so the cap is stale.  Checked against the tree's own formula
  (4*waves_per_simd/waves_per_block, LDS cap 128K/lds) over the patched gfx1030 HSACO: every
  D=256 shape the launcher can now pick reports >= 2 blocks, so the
  GGML_ASSERT(max_blocks_per_sm > 0) abort the cap guarded against is unreachable.
- the checked tail clamps out-of-range rows to the last in-bounds row instead of branching to
  a local zero array.  The tail values are discarded by the k_VKQ_sup guards, every read stays
  inside the cache, and the pointer-select the branch existed to avoid (the kv=113
  flat-scratch fault) is gone with it.  i_sup - 1 may be -1 (a V chunk wholly past the KV
  end): row -1 is the last VALID row, and every weight in that chunk is zero, so the comment
  in the loader says so and warns against "fixing" it to max(i_sup - 1, 0), which would read
  one row past the cache.

Verified here on ROCm 10.1.0 against this tree: both levers compile for gfx1030 (all 12
template-instances tile TUs, no warnings), the D=256 4x8/16x2 checked-tail scratch goes
480/500 B -> 0 B (the submitter's 488/520 on their toolchain), the largest static LDS in the
whole tile family stays 63488 B of gfx1030's 65536 B, and for gfx1201 every tile kernel's
machine code is bit-identical before and after (88/88 and 106/106 kernels hashed per kernel),
so RDNA4, RDNA3_0, RDNA3_5, NVIDIA and MUSA/SYCL keep their codegen and numerics exactly.
The timings stay the submitter's (pp2048 @ d32768 1041.0 -> 1259.8 t/s, tg256 @ d131072
50.9 -> 62.4 across their two arms); RDNA2 is best-effort per CONTAINERS.md and carries no
gate in this repo.

Not taken from the PRs: their own patches-rdna2-r205/ + release-rdna2-r205.json +
scripts/apply-rdna2-r205.sh re-packaging (the same call as r88), and the block 16 two-lane
prefill the branches were stacked on (PR ggml-org#268, a separate candidate).
… derived kq mask

Band (RDNA4 WMMA GQA fold, wide verify band, GQA cap ggml-org#133, the
ggml_set_fa_tensor_parallel hint), native quantized q8_0/q4_0/q4_1/q5_0/q5_1/
iq4_nl/bf16 K/V reads, the V3 derived kq-mask inputs (cell_pos/tok_lo/tok_hi),
the iq4_nl FA quants and the per-type tile instances.

The per-context fattn_stage prefill arena (and its RDNA3_5 prefill band split)
is deferred to block 10 slab-moe: here a native-capable operand is read natively
at every width and the F16 staging copy for a non-native type goes to the node's
reserved scratch (the pre-arena behaviour).

Env-read hygiene (no behaviour change): resolve GGML_CUDA_FA_WMMA_256 / GGML_CUDA_FA_WMMA_MAX_HEAD
once into values rather than caching the getenv() pointer (unsafe on Windows).

RDNA2 (gfx1030) FA gate fixes, reported and validated by @slavap (PR ggml-org#181;
Radeon Pro V620 + RX 7900 XTX, ROCm 7.2.4, one gfx1030;gfx1100 build, the full
FLASH_ATTN_EXT and MUL_MAT backend-ops gates green on both cards).  Without them
the gfx1030 FLASH_ATTN_EXT gate aborted with "ROCm error: an illegal memory
access" and MUL_MAT was blocked behind it.  Three separate defects:

- ggml_cuda_flash_attn_ext_get_alloc_size (TILE branch): FATTN_KV_NATIVE_BF16
  is the *F16 staging* type on hardware without native BF16 tensor cores -- the
  tile case chooser only picks the BF16 instantiation under
  bf16_mma_hardware_available, and gfx1030 has no V_DOT2_F32_BF16 -- so mapping
  it to GGML_TYPE_BF16 left need_f16 false and let the whole-cache converter
  write past the node's allocation (sentinel clobber, then illegal access).
  The mapping now matches the chooser.  The same latent mismatch existed on
  RDNA1 and on pre-Ampere NVIDIA / older MUSA.
- launch_fattn_tile_switch_ncols1: the decode/verify band (Q->ne[1] <= 8) was
  the only one of the seven launch sites that omitted the q_h2 argument, so it
  defaulted to false while a wide RDNA2 kernel (q_global: GGML_CUDA_FATTN_TILE_
  Q_GLOBAL, DKQ <= 256, ncols >= 16) read Q from the Q_h2 global half2 buffer
  that was never allocated -- a null pointer and a fault near 0x1000 for GQA-16
  decode shapes (hsk=192, nr23=[16,1], n_q <= 8).  It now passes the same
  condition as the other six.
- ggml_cuda_flash_attn_ext_get_f16_extra_data: the ncols2 > 1 tile branch loads
  its KV tiles without out-of-bounds checks, so the last tile reads up to
  nbatch_fa - 1 rows past the operand.  The KV cache allocation has always had
  that slack, but the converted F16 scratch is exact size and sits at the end of
  the node's allocation, so it read into the next allocation.  A 511-row guard
  tail is now reserved after each converted operand (the nbatch_fa config field
  is 9 bits and the table asserts <= 256, so half is margin), gated on
  GGML_CUDA_CC_IS_RDNA2 so every other backend keeps its allocation sizes.

Fold (r92): the 2-byte band arm joins the 32-column band block, and the RDNA4
head-512 row goes back to upstream's shape.  (a) `ggml_cuda_fattn_band_wmma_ncols1()`
no longer special-cases f16/bf16 (native BF16) to 2 columns, and the 2-byte band split
drops from 3*nsm/4 to nsm/2.  The 2-column tile was the right default only while that arm
still selected the pre-band 128-half2 config row: with the band's own 64-half2 row it wins
~5 % at n_q = 1 and loses everywhere else, because ceil(n_q/2) output tiles each stream the
whole KV cache (head 256 GQA 6, gfx1201, us per call, f16 KV: n_q 1 760 -> 684, n_q 4
763 -> 695, n_q 8 1142 -> 823 at kv 98304; bf16 813/869/1451 -> 685/696/832).  The choice
stays width-independent, so W = 1..8 still reduce identically (GREEDY-PURITY.md §36).
(b) The `(512, 512, 32)` RDNA row -- the only head-512 row the AMD dispatcher can reach,
since `switch_ncols1` forces ncols = 32/ncols2 for DKQ > 256 -- was replaced by the
2026-09-14 RDNA prefill sweep with an 8-warp / 128-KV-row / nbatch_V2 16 config that is
~1.35x slower than the tile kernel, which made RDNA4's WMMA head cap of 576 a prefill
regression for every Gemma 4 global layer (issue ggml-org#188).  Retuned to 4 warps, 32 KV rows,
one 128-half2 K/V batch, combine 64, Q in registers: gemma-4 31B global-attn shape (D=512,
4 KV heads, 32 Q heads, ub 512, q8_0 KV) 32768 126.1 -> 42.3 ms and 98304 377.0 -> 128.1 ms,
end to end pp512 +95 % at d32768 and +144 % at d98304 (31B and 26B-A4B).  Records:
archive/work/fa-band-2byte-row/, upstream/UPSTREAM-PR-fa-512-rdna-head-cap/.

Fold (r98, PR ggml-org#195, @overdoingism): with q8_0 K and V read in place (decode/verify, up to 8 query rows)
the RDNA4 band launches a second kernel variant, `flash_attn_ext_f16<..., band_fetch_ahead = true>`, which
fetches the raw q8_0 bytes of the next K/V batches into registers ahead of use and converts a batch into
shared memory only when it is due; its barriers order shared memory only (release / s_barrier / acquire on
"local"), because `__syncthreads()` also waits for every outstanding global load and would drain the fetches
at the next barrier.  The quants stay packed in 32-bit words, with an empty `asm volatile` pinning the
conversion at the stage point (otherwise the compiler unpacks the bytes right after the fetch, which waits
there and needs 4x the registers).  64-column block (widths 5..8): two batches in flight, Q in registers.
32-column block (widths 1..4): one batch in flight and the stream continues across the iteration boundary
into the next KV block that is not fully masked, Q read from shared memory (a register-resident Q is spilled
there and its scratch reloads share the load counter with the fetched K/V).  The variant is compiled in two
generated translation units of its own (`template-instances/fattn-mma-f16-band-fetch-ahead-ncols1_{4,8}-
ncols2_8-dkq256-dv256.cu`, emitted by generate_cu_files.py), so every other launch, including f16 / bf16 K/V
and prefill, compiles to the same gfx1201 instructions as before it (verified at the assembly level: 0
differing instructions in both dkq256 band instances, a dkq128 instance, the tile and vec units and
fattn.cu).  Default on; `GGML_HIP_FA_BAND_FETCH_AHEAD=0` runs the kernel without it for q8_0 too.  It also
keys the FA shared-memory attribute raise per (variant, device) rather than per device, so the two kernels
cannot share one "already raised" flag.

Gates (gfx1201, ROCm 10.1.0, 27B UD-Q4_K_XL with q8_0 K/V unless noted): bit-identical to r97 everywhere
the variant fires -- `test-backend-ops -o FLASH_ATTN_EXT` 6391/6391 on both builds, prefill-logit KLD
0.000000 / same-top-p 100.000 %, greedy text identical at 8K and 110K context, on a 2 GPU tensor split and
on gemma4 12B (its head-256 SWA layers), the 4-axis adaptive MTP gate at -n 3000 (text and draft acceptance
identical on all four axes) and n7 = plain; `llama-batched-bench -npp 16 -ntg 32 -npl 1,4,8` B=1 29.47 ->
30.12 t/s, B=4 95.73 -> 97.70, B=8 flat; decode +0.7 % at 8K and +2.4 % at 110K context (3 interleaved pairs
each; prefill unchanged at 840 t/s), +0.9 % on the 2 GPU tensor split.

Fold (r99, PR ggml-org#198, @slavap): two RDNA2 (gfx1030) FA follow-ups from the review of PR ggml-org#181, plus the
arch-independent half they needed.

- **One tile K/V type selection.**  The tile kernel has a single K/V type parameter and its choice was kept
  by hand in two places: the instantiation (`ggml_cuda_flash_attn_ext_tile_case_type`, `fattn-tile.cu`) and
  the F16 scratch sizing (`ggml_cuda_flash_attn_ext_get_alloc_size`, `fattn.cu`).  They had drifted three
  times (the missing q4_0 arm, the mixed-K/V NaNs, the missing RDNA2 bf16 scratch).  Both now call one
  `ggml_cuda_fattn_tile_type(K, V, cc)` in `fattn-rdna.cuh`: BF16 only where the hardware reads it natively,
  else the native dequant type, else F16 (BF16 without native support maps to F16, i.e. the launcher
  converts).  The mapping is 1:1 with the previous order on every arch, the instantiation set is unchanged
  (96 tile objects before and after) and the host change leaves every tile kernel's gfx1201 ISA identical.
- **Checked tail for the last unchecked tile (RDNA2 only).**  The `ncols2 > 1` tile branch loads its KV
  tiles without out-of-bounds checks, so its last tile can read up to `nbatch_fa - 1` rows past the KV data.
  In a model that stays inside the KV cache tensor's slack, but an exact-size operand (test-backend-ops) can
  reach the neighbouring allocation.  On RDNA2 the last tile now takes the already-compiled
  `oob_check = true` form (zero-fills the tail and keeps it out of the softmax).  Every other target is
  untouched: `RDNA2` is defined only in the gfx103x device pass (`vendors/hip.h`), the added block is inside
  `#if defined(RDNA2)`, and the gfx1201 tile instances are byte-identical in ISA to r98.
- **The 511-row guard tail is kept** and its derivation documented: `nbatch_fa` is a 9-bit config field but
  `GGML_CUDA_FATTN_TILE_CONFIG_CASE` static_asserts `<= 256`, each K chunk loads `nbatch_fa` rows and each V
  chunk `nbatch_V` with `static_assert(nbatch_fa % nbatch_V == 0)`, so the over-read is at most `255` rows;
  511 = 2 x 256 - 1.  Since the RDNA2 tail is now checked, the tail is belt-and-braces, not the only
  protection.  Comment only: no allocation size changes on any backend.

Gates (gfx1201, ROCm 10.1.0): `test-backend-ops -o FLASH_ATTN_EXT` 6391/6391 (identical per case to r98),
prefill-logit KLD 0.000000 / 100.000 %, greedy text identical to r98, `validate-set.sh` green, per-block
build green.  A `gfx1201;gfx1030` dual-target build compiles the RDNA2 arm; the RDNA2 runtime gate is the
reporter's (Radeon Pro V620, ROCm 7.2.4: FLASH_ATTN_EXT 6389/6389, MUL_MAT 2444/2444 with the add-on, and
the same on gfx1100).

RDNA3_0 (gfx1100) head-512 WMMA prefill rows, reported by @briansp2020 (PR ggml-org#199;
RX 7900 XTX).  The RDNA head-512 rows were tuned on gfx1201 and keep Q in
registers, so on gfx1100 every head-512 kernel sat at the 256-VGPR limit and
spilled (~1.0-1.4k VGPRs per lane); head 512 was therefore capped back to the
tile kernel on RDNA3_0 in r5 (issue ggml-org#30).  RDNA3_0 now has its own rows for
DKQ == DV == 512 (Q in shared memory, 128 threads, 64-wide K/V/combine
batches), and head 512 takes WMMA prefill again on top of the 256 cap: other
heads above 256 keep the tile kernel, RDNA4/RDNA3_5 rows are unchanged and the
decode/verify band stays on the tile kernel.  GGML_CUDA_FA_RDNA3_WMMA_512=0
disables it; GGML_CUDA_FA_WMMA_256=0 and GGML_CUDA_FA_WMMA_MAX_HEAD still take
it out (the rows are RDNA3_0-only, so MAX_HEAD only decides whether head 512
takes WMMA at all).

Measured on gfx1100 (gemma-4-26B-A4B QAT UD-Q4_K_XL, q8_0 KV, pp2048):
d32768 1908.3/1909.2 -> 2549.1/2554.6 t/s (+34 %), d65536 1209.3/1207.6 ->
1756.2/1757.5 (+45 %), tg128 at d32768 unchanged (127.74/127.74 ->
127.80/127.73).  FLASH_ATTN_EXT 6391/6391 on gfx1100; the switch-off text is
bit-identical to r101 and gfx1201/gfx1151 output is unchanged (byte-identical on
gemma4-26B-A4B).

Prefill-logit NOTE (known limitation, TODO ggml-org#81 / wip/fa-rdna3-head512-purity):
this is a tile->WMMA family switch, so it moves the prefill logits against the
tile kernel: mean KLD 0.0293 / same-top-p 92.59 % on that model at the gate's
out-of-domain point (PPL 604), i.e. it does NOT meet the absolute 0.005 / 98 %
gate.  Calibrated at the same point: the head-256 WMMA rows the delivery has
shipped default-on for gfx1100 since r5 measure 0.0441 / 90.63 %, a benign
ubatch change on the same kernel ~0.12 per chunk, and the issue-ggml-org#113 BF16
chunked GDN 0.62.  PPL is unchanged within its +/-5 % error bar (f16 KV 604.06
vs 607.20, q8_0 KV 617.85 vs 620.59).  Accepted as no worse than the shipped
equivalent switch; the campaign above exists to close the gap.

kq-mask fill guards, reported, root-caused and validated by @RikshaDriver (PR ggml-org#222,
issue ggml-org#221; RX 7600 gfx1102, ROCm 10.1, bailingmoe3 / Ling-3.0-tiny-IQ4_NL).  Only a
single-sequence context enables the derived kq form, so the packed mask in
llm_graph_input_mem_hybrid_k is left with no consumer, the allocator gives an
unconsumed input no buffer, and the unconditional fill asserted on it
(GGML_ASSERT(buffer) via llama_kv_cache::set_input_kq_mask) - llama-cli aborted
before the first token.  Ten of the thirteen fill sites in src/llama-graph.cpp
already guard for exactly that; llm_graph_input_mem_hybrid_k and
llm_graph_input_attn_k_dsa (its mla and lid masks) now carry the same guard as
their siblings.  can_reuse needs nothing: can_reuse_kq_mask() reads ne[] only.

The decode/verify band's fully-masked KV group skip, reported by @overdoingism
(PR ggml-org#223, the same reporter whose issue ggml-org#45 the band came from).  The prefill
skip built its packed bitmap under Q->ne[1] > 8, so the band read every other
slot's -INF cells on every decode step - the cost LLAMA_SERVER_LAZY_IDLE_SLOTS
(r130) made common.  The band now gets the bitmap too and its loop, which
already handled it (and had never been reached), skips the fully masked
iterations while keeping its round-robin split: block i still owns i, i+P, ...,
so the accumulation order over the rest is unchanged and the result is
bit-identical.  GGML_CUDA_FA_BAND_SKIP=0 (band arm) / GGML_CUDA_FA_MASK_SKIP=0
(the whole mechanism) turn it off.  Measured gfx1201, 27B UD-Q4_K_XL, 2 slots
unified, q8_0 KV: a resident ~105K conversation behind an active 9.8K one
50.84 -> 41.69 ms/step (-18 %, token ids identical; with a DFlash2 draft at
n-max 5: 18.62 -> 14.83), -0.6 % with nothing to skip.  The delivery adds the
decode-width packed-hole op cases (the band skip had no oracle) and evaluates
the band predicate once for both the skip gate and the 2-D launch.

Co-authored-by: overdoingism <overdoingism@users.noreply.github.com>

Fold (r134, issue ggml-org#224): the band's 64-column block (query widths 5..8) gets its own
geometry and its own instantiation.  A band block's per-column reduction splits the KV
rows of a tile nwarps*cols_per_warp/ncols (np) ways, and that split is part of the width
purity contract: the 32-column block (widths 1..4, 8 warps, np 4) and the 64-column block
must split them identically, or greedy decode with a draft differs from decode without
one.  r126 removed the 16-warp row for ncols 64 (it was also the prefill instantiation),
which left widths 5..8 on prefill's 8-warp table row (np 2) -- a reordered reduction,
~1e-3 relative, invisible to every throughput number, same-seed text gate and
CPU-referenced op test, and reported as an 8K/110K greedy divergence on dense head-256
GQA-6 (Qwen3.8-27B + DFlash2, plain != draft on r131, identical with
GGML_HIP_FA_BAND_WIDE=0 and on r123).  The 16-warp band row is back
(fattn_mma_config(512, 1, 64, 64, 64, 32, 1, true), nbatch_combine 32 to stay inside the
64 KiB LDS limit at 16 warps), selected by a new compile-time `band_wide` flag threaded
through the config getters, the case function and the kernel, so prefill keeps the
256-thread table row and its deep-prefill win (pp512 @ d98304 unchanged).  The band's
64-column case + its q8_0 fetch-ahead variant are separate translation units
(template-instances/fattn-mma-f16-band-wide-*.cu, emitted by generate_cu_files.py).
A static_assert on the two band rows (np and the KV batch shape must match) makes this
class of regression a build error.

Fold (r164, PR ggml-org#242, overdoingism): `llm_graph_input_kq_derived::can_reuse()` looks through a
`llama_memory_hybrid_context` to its attention cache.  A hybrid model's `params.mctx` is the wrapper, never the
`llama_kv_cache_context` the input was built from, so the derived input rejected reuse for *every*
single-sequence batch of more than 8 tokens - and since `LLAMA_KV_N_PAD_MIN` holds `n_kv` on the 256-cell
stride the derived form's own gate requires, those batches really did take the derived form, so each one
rebuilt its graph: a 9-16 row n-gram verification step, or an MTP verify step at
`--spec-draft-n-max >= 8` (0 graphs reused over 300 decode tokens at a fixed depth 15, i.e. 6820 -> 6338 ms
on 3 GPU `-sm tensor` and 5329 -> 5041 ms at 2 GPU, +7.6 % / +5.7 % - against this block's own
`LLAMA_KQ_MASK_DERIVED=0`).  `get_attn()` is exactly the cache `build_inp_mem_hybrid()` built the input from,
and the existing checks (n_kv, stream count, token count, `kq_mask_derivable()`) then run against it
unchanged, so reuse returns to parity with the packed path (n-gram n_max 15 on 1 GPU: 58 -> 77 reused =
the packed arm; 3 GPU: 0 -> 97) with greedy text and draft acceptance byte-identical on every arm.  iSWA
still rejects, necessarily: `build_inp_mem_hybrid_iswa()` creates *two* derived inputs (one bound to the base
cache, one to the SWA cache), so there is no single cache to look through.  `LLAMA_KQ_MASK_DERIVED_REUSE=0`
restores the rejection.

Fold (r172, PR ggml-org#247, overdoingism): the derived kq mask covers batches of several sequences, so a
`--parallel > 1 --kv-unified` context stops reserving the packed mask (n_kv x n_ubatch x 2 bytes on each
device and again pinned on the host).  Sequence k of the ubatch has its cells and its tokens' [lo, hi]
shifted by k * 2^23 (KQ_DERIVED_SEQ_STRIDE), so the existing `tok_lo <= cell_pos <= tok_hi` predicate
keeps every token inside its own sequence's range and the FA kernels need no change.  The form is taken
only when one KV stream holds the batch, every token is in exactly one sequence, no cell carries two of
the batch's sequences (`llama_kv_cells` now counts those, so the check is O(1) unless
`llama_memory_seq_cp` was used) and every position is below the stride; a multi-sequence batch of at most
32 tokens (the multi-slot verify steps) and every other refused shape keeps the packed mask.
`kq_mask_packed_reachable()` drops its `n_seq_max > 1` term, and `decode()` latches
`kq_mask_multiseq_seen` on the first pre-split batch the form cannot serve and re-reserves once with the
packed mask (the r160 2-D latch pattern, so no later batch grows the compute buffer - issue ggml-org#42).
Measured (gfx1201, dense 27B UD-Q4_K_XL, `-c 245760 -ub 2048 --parallel 2 --kv-unified -ctk/-ctv q8_0`):
device memory 27.51 -> 26.41 GB and server RSS 1.97 -> 0.98 GiB after load, two concurrent 16K prefills
unchanged (26.96 vs 27.23 s at 1 GPU; 17.07 vs 17.09 s at 2 GPU `-sm tensor`), single-sequence greedy text
byte-identical (dense / 35B-A3B MoE / hybrid 4B) and `plain == draft-mtp` identical.
Purity: the derived predicate *is* the packed one - the author's host oracle compares the two fills cell
by cell, re-run here with 0 mismatches on llama-perplexity at 4 sequences per ubatch (dense 27B at 1 and
2 GPU tensor, Qwen3.5-4B hybrid, Gemma4-12B and gpt-oss-20b iSWA) and on the 2-slot server shape; the
prefill-logit gate at `--ub 2048 --ab "LLAMA_KQ_MASK_DERIVED_MULTISEQ=0"` reads 0.000000 / 100.000 % at
both f16 and q8_0 KV, and `gate-park-idle-slots.sh` passes at 3 GPU tensor.  No effect on a graph that
also holds an `allow_derived = false` builder (qwen4exp/QSA, MLA): its packed mask is created and filled
anyway - measured identical VRAM and RSS on Flash-Next.  `LLAMA_KQ_MASK_DERIVED_MULTISEQ=0` restores the
single-sequence rule and the packed reserve.

Fold (r208): RDNA2 (gfx1030) FA prefill, reported and validated by @slavap (PR ggml-org#270/ggml-org#271;
Radeon Pro V620 gfx1030, Qwen3.6-35B-A3B IQ4_XS, -b 8192 -ub 2048 -fa 1).  This is the RDNA2
long-context deficit of issue ggml-org#214, and it is folded here rather than cut as new blocks.

- q_global threshold 16 -> 64: the two kernel-side conditions, the Q_tmp_count stub and all
  seven launcher q_h2 arguments move together (a launcher that omits the argument is the r88
  null-Q_h2 fault).  At ncols 16..32 the global-half2 Q path re-reads Q per K-tile pass and
  the checked tail spilled ~180 VGPRs; with Q back in LDS it does not.
- rdna_cap_ncols2 lifted for DKQ == 256 (D=128 keeps the cap).  The cap dates from r76, when
  HIP's RDNA2 occupancy query returned 0 for the wide D=256 variants; launch_fattn computes
  RDNA2 occupancy itself now, so the cap is stale.  Checked against the tree's own formula
  (4*waves_per_simd/waves_per_block, LDS cap 128K/lds) over the patched gfx1030 HSACO: every
  D=256 shape the launcher can now pick reports >= 2 blocks, so the
  GGML_ASSERT(max_blocks_per_sm > 0) abort the cap guarded against is unreachable.
- the checked tail clamps out-of-range rows to the last in-bounds row instead of branching to
  a local zero array.  The tail values are discarded by the k_VKQ_sup guards, every read stays
  inside the cache, and the pointer-select the branch existed to avoid (the kv=113
  flat-scratch fault) is gone with it.  i_sup - 1 may be -1 (a V chunk wholly past the KV
  end): row -1 is the last VALID row, and every weight in that chunk is zero, so the comment
  in the loader says so and warns against "fixing" it to max(i_sup - 1, 0), which would read
  one row past the cache.

Verified here on ROCm 10.1.0 against this tree: both levers compile for gfx1030 (all 12
template-instances tile TUs, no warnings), the D=256 4x8/16x2 checked-tail scratch goes
480/500 B -> 0 B (the submitter's 488/520 on their toolchain), the largest static LDS in the
whole tile family stays 63488 B of gfx1030's 65536 B, and for gfx1201 every tile kernel's
machine code is bit-identical before and after (88/88 and 106/106 kernels hashed per kernel),
so RDNA4, RDNA3_0, RDNA3_5, NVIDIA and MUSA/SYCL keep their codegen and numerics exactly.
The timings stay the submitter's (pp2048 @ d32768 1041.0 -> 1259.8 t/s, tg256 @ d131072
50.9 -> 62.4 across their two arms); RDNA2 is best-effort per CONTAINERS.md and carries no
gate in this repo.

Not taken from the PRs: their own patches-rdna2-r205/ + release-rdna2-r205.json +
scripts/apply-rdna2-r205.sh re-packaging (the same call as r88), and the block 16 two-lane
prefill the branches were stacked on (PR ggml-org#268, a separate candidate).


This adds an option to compute perplexity over the prompt input similar to https://huggingface.co/docs/transformers/perplexity. It does so by chunking up the prompt into non-overlapping chunks of the context window size. It then runs the forward pass and computes the softmax probability of the output logits for the last half of the context window. This is so the model always has some context to predict the next token. Be warned: it is pretty slow, taking about 4 hours or so to complete wikitext2 on a 32 core machine.
Note: when doing prediction over large prompts, the default 10% expansion for the memory buffer is not sufficient - there is definitely a non-linear scaling factor in there somewhere.
Example:
./main --perplexity -m models/7B/ggml-model-q4_0.bin -f wiki.test.rawperplexity: 6.5949 [655/655]Some example runs at context 512:
Context 1024 runs:
Which show that the 16 bit version of the model is the best (lower perplexity is better), the 4 bit quantization introduces a fair amount of error (but not disastrous certainly), and the
--memory_f16flag is almost identical to baseline 4 bit.Comparing to this article: https://nolanoorg.substack.com/p/int-4-llama-is-not-enough-int-3-and, where they compare 4-bit to GPTQ quantization. The results are comparable, which is a good sign!
